mercredi 8 octobre 2014

Ubuntu login analysis

I'm tracing a lot these days, and in the viewer, I need to scroll a lot to get to the interesting stuff in the control flow view. Today, I checked all these processes for fun. In fact, it's related to landscape triggered on Ubuntu login. To display the message about system usage and updates (which I think is great), landcape calls numerous sub-programs, for a total of about 250ms on my system. It's something one should keep in mind if SSH commands are repeated in a tight loop: the maximum rate is about 4 commands per seconds. Hopefully, Fabric reuses SSH connection! ;-)

Ubuntu login greeting

The active path of the computation of the login greeting


mercredi 6 août 2014

Pinpoint memory usage of Java program with Eclipse Memory Analyzer

My Java program was using a lot of memory. An object was holding a reference on a large temporary data structure, even after it was out of scope. It is indeed difficult to understand what prevent the garbage collection to do its job. Here is how I found out.


  • Download and extract Eclipse Memory Analyzer (MAT).
  • Download the HeapDump.java class and insert a call to HeapDump.dumpHeap() after the point your think the memory should be released.
  • Run the instrumented program. The resulting file size may be rather large (seems to be the hole VM memory), so make sure you have enough free space.
  • Open it in MAT. (Notice: I was experiencing a hang bug on Ubuntu 14.04, dismiss the initial report dialog and do not generate HTML reports, it seems to trigger the bug). Click on Dominator Tree.
  • Once you found the offending object, right click on it and select Path to GC Roots > with all references. This will display the references that prevent the GC to free this object.
  • Fix the code and you can start over to verify that the problem is indeed fixed ;-)


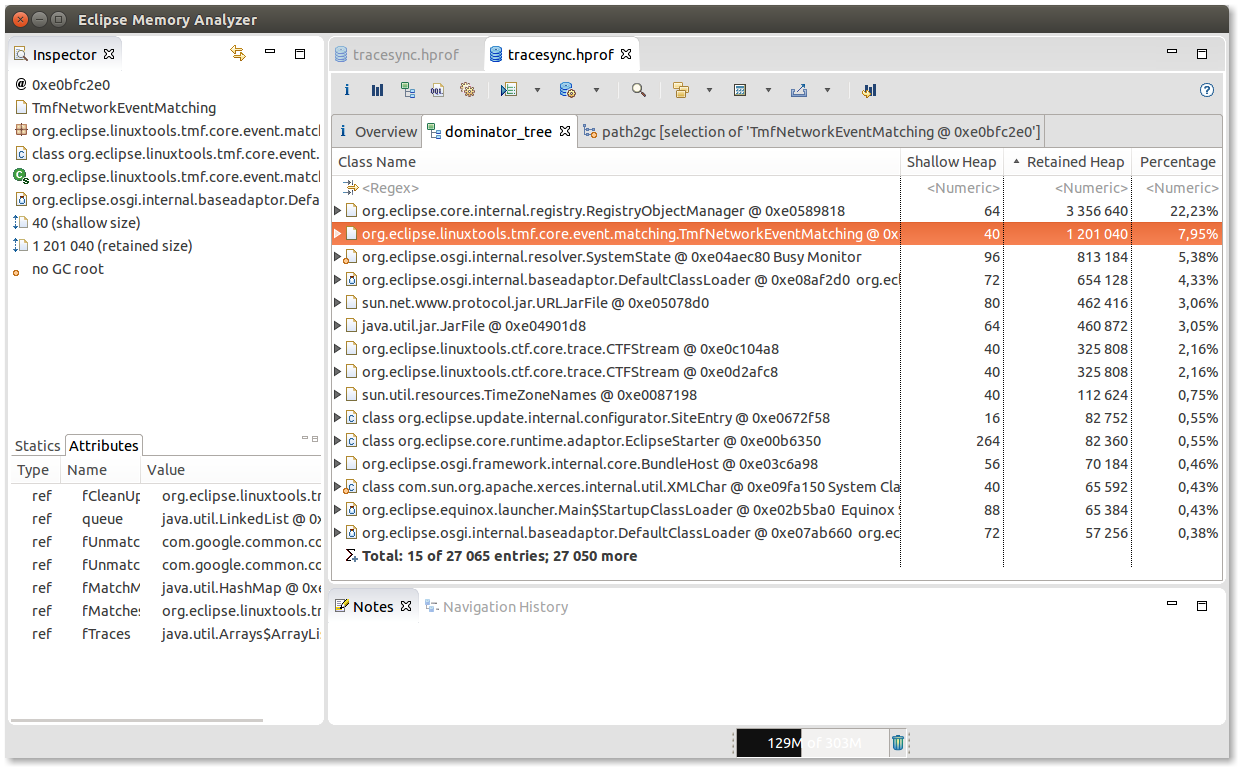
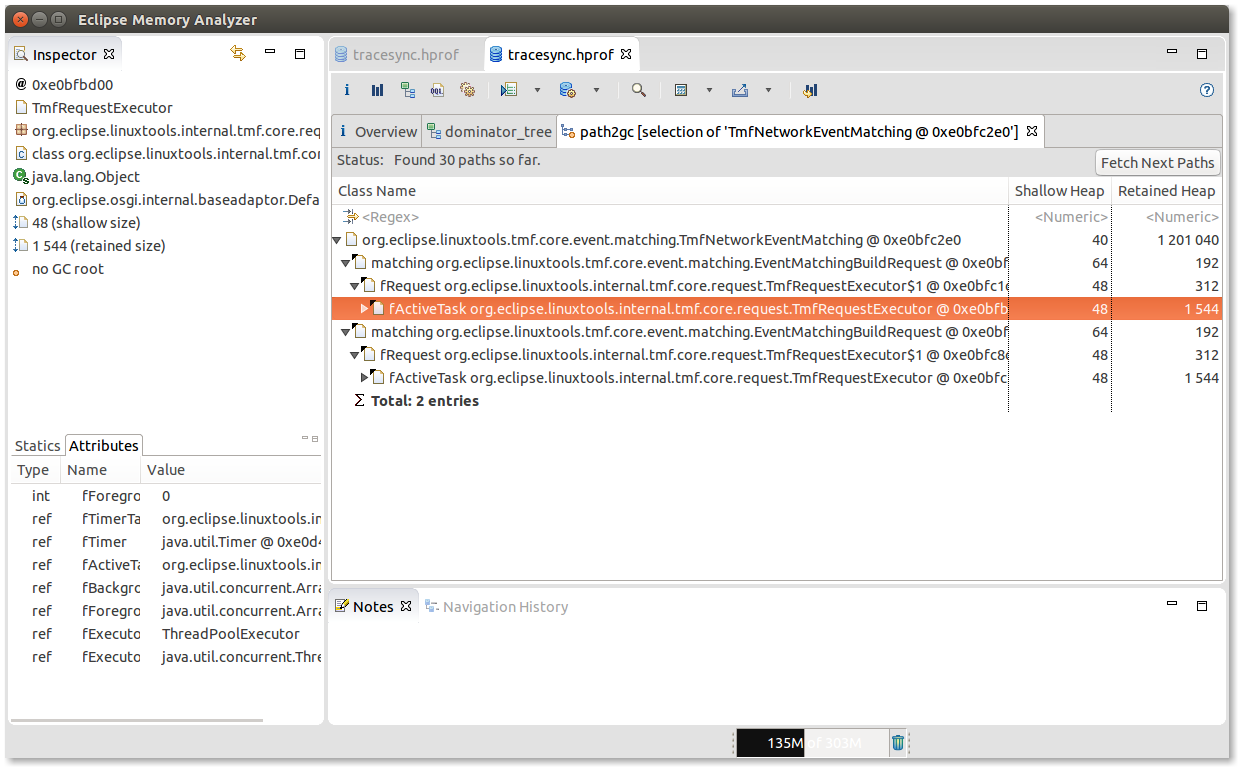
The following screenshots shows an example of the tool usage for my problem. The class TmfNetworkEventsMatching matches send to receive network events in a trace. Unmatched packets are kept temporarily in memory. However, the old unmatched packets were never freed. In the Dominator Tree, we see that TmfNetworkEventsMatching is 40 bytes (Shallow Heap), but holds around 1.2MB of objects (Retained Heap). The Path to GC Roots highlights that a reference of TmfNetworkEventMatching is kept inside TmfRequestExecutor. In this case, a missing call to dispose() was preventing the release of resources. Other resources are auto-closable, except for one of them, which needs manual call to dispose(). Thank you MAT!

Dominator Tree

Path to GC Roots

jeudi 29 mai 2014

Performance comparison of CTF trace readers

I'm implementing a kernel trace analysis using the Java CTF reader, and I wanted to know if I would increase the performance by going with the babeltrace reader in C. Here are my findings.

One of the expansive step of trace analysis is the actual trace reading. It consists to read the binary trace and retrieve the timestamps, the event type and the value of each fields. The event is then added to a priority queue for reading multiple streams in order. We compare three trace readers, namely the Babeltrace reader 1.2 (C implementation, dummy output format), the Java CTF reader and the Eclipse TMFEventRequest (which uses the Java CTF reader as back-end). We compare the trace reading in cache cold conditions (drop_caches prior to reading) to when the trace is resident in page cache. I ensure that the lazy loading of fields values are effectively loaded in all cases, but without printing the content. The trace size is 855MB and contains 22 million kernel events from a Django web app benchmark (recorded with lttng), and it takes between 20s and 80s to process the trace. The drive used is an SSD Crucial M500 1TB, and the host is an i7-4770 with 32GB of RAM. The following figure shows the performance results in thousands of events per second.


We observe that babeltrace is roughly 2 times faster than the CTFTraceReader in Java, and about 3.5 times faster than TmfEventRequest. I measured also the CPU usage, and the processing is mostly serial and single threaded in every cases, so babeltrace seems effectively more efficient.

The other important observation is that trace parsing is CPU bound, not I/O bound. Reading a trace from a hard drive is certainly I/O bound, but it's not the case with SSD. The difference between cache cold and cache hot is between 2% and 5% either in Java or in C. It means we could probably speed-up the reading using parallel threads.

In conclusion, both the C and the Java libraries provides acceptable performance level for CTF trace reading. For high-performance processing, the babeltrace library is preferable. The CTFTraceReader provides nonetheless a good performance, and may be a compromise between the rapid development and runtime efficiency. If abstracting the trace source is a requirement, then TMF is what you need, but you now know the cost of this additional flexibility. Yours to choose!

Notice: the TMFEventRequest can be done either with ExecutionType.FOREGROUND or ExecutionType.BACKGROUND. The background parameter introduce delays (sleeps) and reduces the throughput. Use the foreground parameter to reduce processing time and improve UI interactivity, but uses background for low priority processing.

jeudi 5 décembre 2013

System-level profiling of APT

APT is the package manager of Debian based distributions. Understanding where the time is spent installing a package is difficult, because there are numerous process involved. We discuss limitations of profiler tools and present system-level trace analysis that highlight waiting between tasks.

Callgrind is a profiler that helps to find hotspot in the application. One limitation of a profiler is that the time spent waiting is not taken into account, for instance I/O, resources or other tasks. This situation is shown in figure 1, where we traced the command "sudo apt-get install tree --yes". The actual computation done in the apt-get process accounts for 63% of the elapsed time, while waiting time is about 37%. The callgrind results covers only instructions from the application, not the waiting time.

Figure 1: State of apt-get process according to time.

How to effectively understand what the application was waiting for? For this matter, we performed a waiting dependency analysis on all tasks on the system. The event sched_wakeup indicates the waiting source. Figure 2 shows the result of waiting dependencies among tasks for the command.

Figure 2: Overview of  apt-get waiting dependencies according to time.
The analysis resolves waiting time recursively. In this run, apt-get process is waiting for dpkg, and it accounts for about 20% of the execution time. Figure 3 shows the wait I/O that occurs in dpkg, up to the kernel thread responsible for the file system journal of the partition on which the I/O is performed.

Figure 3: I/O wait of dpkg according to time.
Another interesting part of the execution is the update of man database performed by mandb. Figure 4 shows that about 200 threads are spawned. In this case, the overhead of starting the threads and setup communication pipe is high compared to the amount of actual work, in consequence running time could be greatly improved by using a thread pool instead.

Figure 4: Execution of mandb according to time.
We located the code responsible for creating all these threads and processes using perf callchain. It seems to be related to how the library libpipeline is working. Here is an example of an interesting call stack:

7ffff729a30b     __execvpe (/lib/x86_64-linux-gnu/libc-2.17.so)
7ffff75a4de4     pipecmd_exec (/usr/lib/x86_64-linux-gnu/libpipeline.so.1.2.2)
409813           [unknown] (/usr/local/bin/mandb)
7ffff75a4e59     pipecmd_exec (/usr/lib/x86_64-linux-gnu/libpipeline.so.1.2.2)
7ffff75a662a     pipeline_start (/usr/lib/x86_64-linux-gnu/libpipeline.so.1.2.2)
408d96           find_name (/usr/local/bin/mandb)
40449c           test_manfile (/usr/local/bin/mandb)
404708           testmandirs (/usr/local/bin/mandb)
405035           update_db (/usr/local/bin/mandb)
40a1c6           mandb (/usr/local/bin/mandb)
40a4fb           process_manpath (/usr/local/bin/mandb)
403777           main (/usr/local/bin/mandb)
7ffff71f9ea5     __libc_start_main (/lib/x86_64-linux-gnu/libc-2.17.so)
403b09           _start (/usr/local/bin/mandb)

At the end of apt-get execution, there is a sleep of 500 ms, shown in blue in the figure 2. Here is the location in the code of this nanosleep, again using perf callchain feature: 

ffffffff816cc0c0 __schedule ([kernel.kallsyms])
ffffffff816cc799 schedule ([kernel.kallsyms])
ffffffff816cb66c do_nanosleep ([kernel.kallsyms])
ffffffff810827f9 hrtimer_nanosleep ([kernel.kallsyms])
ffffffff8108292e sys_nanosleep ([kernel.kallsyms])
ffffffff816d616f tracesys ([kernel.kallsyms])
7ffff72978c0     __GI___libc_nanosleep (/lib/x86_64-linux-gnu/libc-2.17.so)
7ffff7b8ac95     pkgDPkgPM::DoTerminalPty(int) (/usr/lib/x86_64-linux-gnu/libapt-pkg.so.4.12.0)
7ffff7b93720     pkgDPkgPM::Go(int) (/usr/lib/x86_64-linux-gnu/libapt-pkg.so.4.12.0)
7ffff7b26585     pkgPackageManager::DoInstallPostFork(int) (/usr/lib/x86_64-linux-gnu/libapt-pkg.so.4.12.0)
415a1b           [unknown] (/usr/bin/apt-get)
418dfc           [unknown] (/usr/bin/apt-get)
7ffff7af96c2     CommandLine::DispatchArg(CommandLine::Dispatch*, bool) (/usr/lib/x86_64-linux-gnu/libapt-pkg.so.4.12.0)
40a2ec           [unknown] (/usr/bin/apt-get)

Here is the detail of pkgDPkgPM::DoTerminalPty() function from apt/apt-pkg/deb/dpkgpm.cc:

/*
 * read the terminal pty and write log
 */
void pkgDPkgPM::DoTerminalPty(int master)
{
   unsigned char term_buf[1024] = {0,0, };

   ssize_t len=read(master, term_buf, sizeof(term_buf));
   if(len == -1 && errno == EIO)
   {
      // this happens when the child is about to exit, we
      // give it time to actually exit, otherwise we run
      // into a race so we sleep for half a second.
      struct timespec sleepfor = { 0, 500000000 };
      nanosleep(&sleepfor, NULL);
      return;
   }
   if(len <= 0)
      return;
   FileFd::Write(1, term_buf, len);
   if(d->term_out)
      fwrite(term_buf, len, sizeof(char), d->term_out);
}

The comment mentions a possible race, but the caller may be fixed to account for this situation. IMHO, this function should not sleep if an error occurs while reading the file descriptor, and should instead return immediately.

This was a small example of what can be achieved with the waiting dependency analysis from a kernel trace. The analysis plug-in will be available soon in Eclipse Linux Tools, and uses standard tracepoints from the Linux kernel, recorded with LTTng. I hope that this information will help the community to improve performance of installing packages with APT. 

Cheers!

The APT licence plate! (thanks to Yannick)


vendredi 7 juin 2013

How slow is Java reflection?

I use Java reflection for trace analysis, as a way to call hooks when specific events are encountered. I wanted to know the overheard related to using such dynamic invocation. First, here is a small example of a trace event handler.

public class FooTraceEventHandler extends TraceEventHandlerBase {

  public FooTraceEventHandler() {
    super();
    this.hooks.add(new TraceHook("sched_switch"));
  }

  public void handle_sched_switch(TraceReader reader,
                                  CtfTmfEvent event) {
    // Process event
  }
}

By convention, the function "handle_sched_switch" is called only with an instance of "sched_switch" event as argument. The magic happens by first getting a reference the method by it's name (done once), and then call it dynamically later in the processing path, similar to the following small example.

method = dummy.getClass().getMethod("foo", (Class[]) null);
...
method.invoke(dummy);

To compare dynamic invocation to compile-time method call, I did a trivial benchmark program. Here are the results for 10 billion calls.

StaticMethodBenchmark     9,653000
DynamicMethodBenchmark    47,625000

This experiment shows that dynamic invocation is roughly 5x slower than compile-time method call. Dynamic invocations is also weaker, because a missing method for the corresponding hook will be detected only at runtime.

There are benefits to using hooks. The test for the event type is done only once for all handlers. It avoid quite a lot of repetition. Also, it allows to list events required for a specific analysis, and then enable only this subset in the tracing session, reducing the runtime overhead and the trace size compared to enabling all events. So, we need to preserve these properties, but with compile-time invocations.

mardi 4 juin 2013

How-to setup LTTng on Fedora 19

Here is how to install lttng including kernel and userspace tracing on Fedora 19 beta.

Instructions uses sudo. To configure sudo on your fedora system, use this command as root, and replace  [username] with your username, then logout and login again:

usermod [username] -a -G wheel


1 Build and install kernel modules


1.1 Perform any pending updates:

sudo yum update

If the kernel is updated, reboot the machine.

1.2 Install development tools:

sudo yum group install "Development tools"

1.3 Fix kernel headers location

At the time of writing this How-to, the version of the kernel-devel package doesn't exactly matches the running kernel (uname -r). We worked around this issue by copying headers in the directory matching the version of the running kernel. The version numbers are likely to change (and this issue may be solved), so adapt it your situation.

First, check if this applies to your system:

rpm -qa | grep kernel-devel
kernel-devel-3.9.4-300.fc19.x86_64

uname -r
3.9.4-301.fc19.x86_64

If versions do not match, you can fix (hack) it like this:

sudo su -
cd /usr/src/kernels
cp -a 3.9.4-300.fc19.x86_64 3.9.4-301.fc19.x86_64


1.4 Download lttng-modules

We need to install lttng-modules 2.2.0-rc2 (or later) for compatibility with linux 3.9.4.

wget http://lttng.org/files/lttng-modules/lttng-modules-2.2.0-rc2.tar.bz2
tar -xjvf lttng-modules-2.2.0-rc2.tar.bz2
cd lttng-modules-2.2.0-rc2/
KERNELDIR=/usr/src/kernels/$(uname -r) make
sudo KERNELDIR=/usr/src/kernels/$(uname -r) make modules_install
sudo depmod -a
sudo modprobe lttng-tracer

The module lttng_tracer should be loaded and visible with lsmod. 


Step 2: Install lttng packages

sudo yum install lttng-tools lttng-ust babeltrace lttng-ust-devel

Now, reboot the machine. The service lttng-sessiond should be started automatically, and all required modules should be loaded. Here is some checks that can be done:

$ lsmod | grep lttng_tracer
lttng_tracer          558145  24 lttng_ring_buffer_client_discard,lttng_probe_jbd2,lttng_probe_kmem,lttng_probe_napi,lttng_probe_scsi,lttng_probe_sock,lttng_ring_buffer_client_mmap_overwrite,lttng_probe_statedump,lttng_ring_buffer_metadata_client,lttng_ring_buffer_client_mmap_discard,lttng_probe_irq,lttng_probe_kvm,lttng_probe_net,lttng_probe_skb,lttng_probe_udp,lttng_ring_buffer_metadata_mmap_client,lttng_probe_module,lttng_probe_signal,lttng_probe_vmscan,lttng_probe_block,lttng_ring_buffer_client_overwrite,lttng_probe_power,lttng_probe_sched,lttng_probe_timer
lttng_lib_ring_buffer    50443  7 lttng_ring_buffer_client_discard,lttng_ring_buffer_client_mmap_overwrite,lttng_ring_buffer_metadata_client,lttng_ring_buffer_client_mmap_discard,lttng_tracer,lttng_ring_buffer_metadata_mmap_client,lttng_ring_buffer_client_overwrite
lttng_statedump        30537  1 lttng_tracer
lttng_ftrace           13097  1 lttng_tracer
lttng_kprobes          12911  1 lttng_tracer
lttng_kretprobes       13224  1 lttng_tracer

$ sudo service lttng-sessiond status
Redirecting to /bin/systemctl status  lttng-sessiond.service
lttng-sessiond.service - LTTng 2.x central tracing registry session daemon
   Loaded: loaded (/usr/lib/systemd/system/lttng-sessiond.service; enabled)
   Active: active (running) since Tue 2013-06-04 14:48:53 EDT; 1min 8s ago
  Process: 385 ExecStart=/usr/bin/lttng-sessiond -d (code=exited, status=0/SUCCESS)
 Main PID: 418 (lttng-sessiond)
   CGroup: name=systemd:/system/lttng-sessiond.service
           └─418 /usr/bin/lttng-sessiond -d

Step 3: Make traces with workload-kit

One way to make traces is to use workload-kit. Here is how to install it from sources.
wget http://secretaire.dorsal.polymtl.ca/~fgiraldeau/workload-kit/workload-kit-0.1.13.tar.bz2
tar -xjvf workload-kit-0.1.13.tar.bz2 
cd workload-kit-0.1.13/
./configure --disable-cputemp
make -j12 
sudo make install
Then, the tool lttng-simple can be used to generate a UST trace or a kernel trace for instance:
lttng-simple -k -s -- sleep 1
babeltrace sleep-k/

lttng-simple -u -- /usr/local/share/workload-kit/scripts/ust/wk-heartbeat
babeltrace wk-heartbeat-u/
Happy tracing!

vendredi 31 mai 2013

Tracing userspace memory allocation

You may wonder what are the actual memory allocations in a program according to time. Here is a method to trace these operations with the LTTng User Space Tracer (UST). Events are recorded by overloading malloc() and free() with a library that is preloaded with LD_PRELOAD. This library is called "liblttng-ust-libc-wrapper.so". To easy the actual tracing session setup, this feature has been added to the lttng-simple utility of workload-kit v0.1.13. By specifying the option "--enable-libc-wrapper", then the environment is set automatically. Here is quick demo to look at the memory allocations of gnome-calculator. (output of babeltrace is simplified for clarity)

// trace the program
$ lttng-simple -u --enable-libc-wrapper -- gnome-calculator

// display events
$ babeltrace gnome-calculator-u/
[10:48:49.808255177] malloc: { size = 40, ptr = 0xCA8220 }
[10:48:49.808256389] free: { ptr = 0xCA8220 }
...

// count events and look for lost events
$ javeltrace analyze -i ctf gnome-calculator-u/...
number of streams                             1
number of packets                         1,058
number of events                        181,879
number of CPUs                                8
number of lost events                         0

This experiment shows that there are about 182 thousands memory allocation events to start a calculator!

Checking for lost events with javeltrace is recommended. The default buffer size in UST is quite small, and in consequence lost events occurs even with very light load, like starting the calculator with memory allocation tracing. The tool lttng-simple setups buffers of 16MB to make it safer.

The next step is of course to display this data according to time and compare it to physical pages allocated by the operating system with a kernel trace.

Happy hacking!